Engineering partnership · Data Solutions

Cognitive Storage Engine

Connect every data source, understand every file, and keep sensitive data under control.

Know what data you hold, who can see it and when it should go.

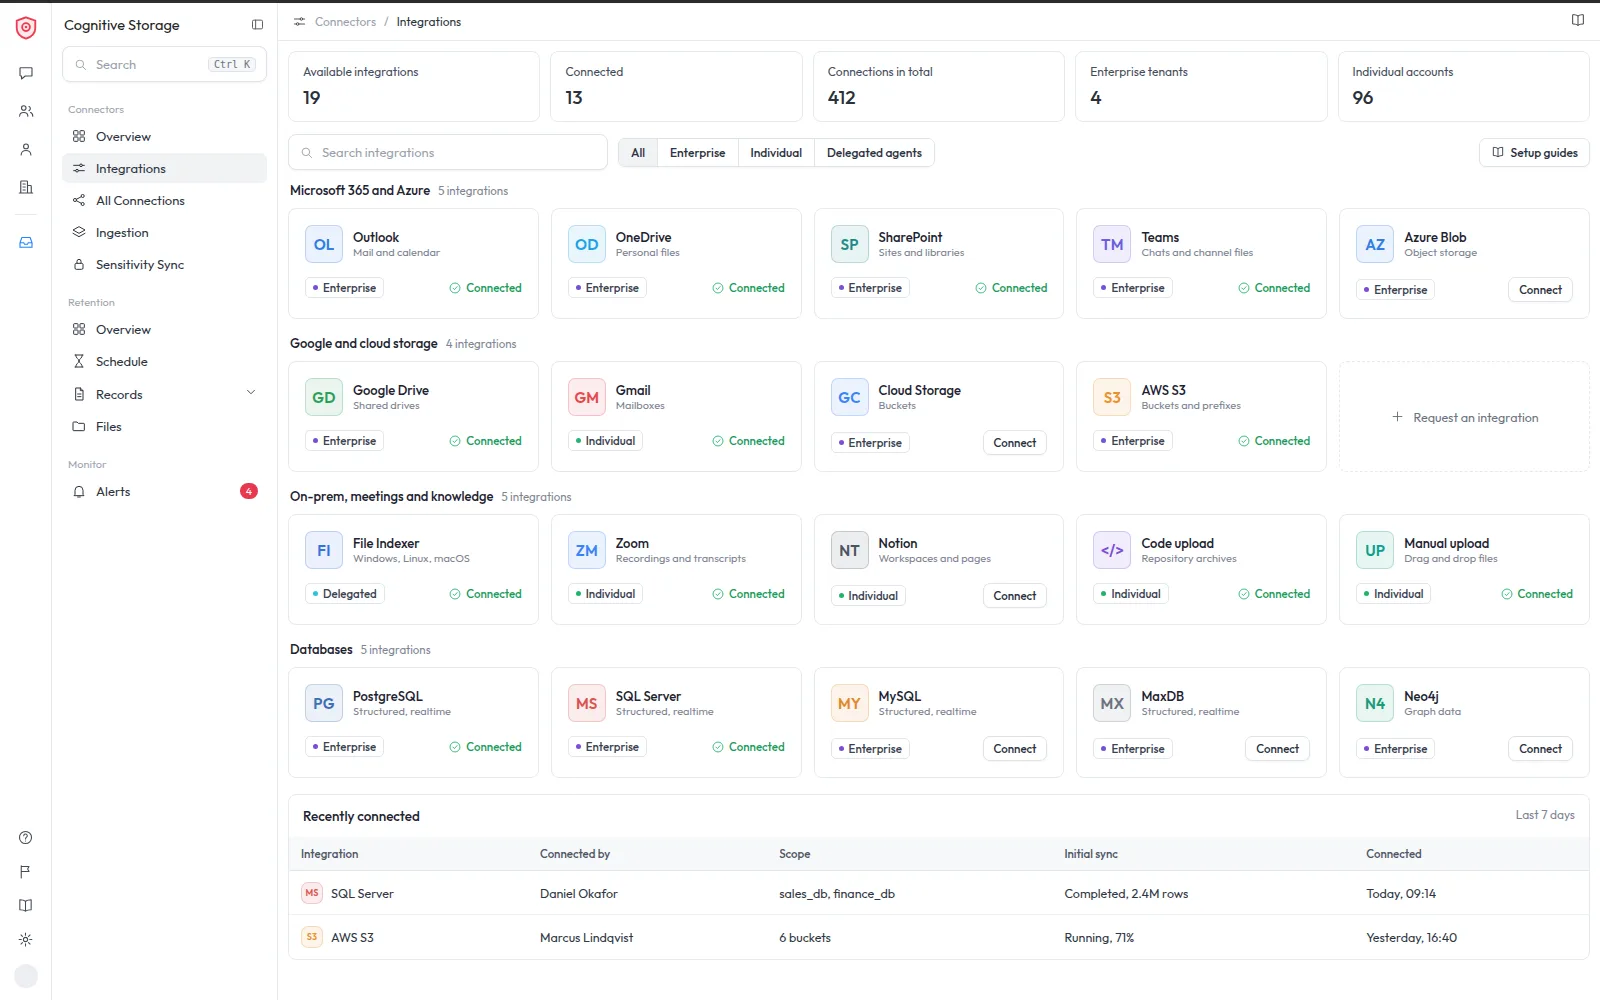
Integrations hub with Microsoft, Google, AWS, database, Notion and code sources, each marked enterprise, individual or delegated.
Data Solutions

See it in action

An AI-governed data platform. It ingests content from cloud, on-premise and database sources, classifies and labels every item, writes sensitivity back to the source, powers search and chat over your data, and enforces retention with a human in the loop (HITL) at each step.

  • 0connectors
  • 0enrichment signals
  • 0modules
Integrations hub with Microsoft, Google, AWS, database, Notion and code sources, each marked enterprise, individual or delegated.
One hub, every source

01Integrations

Connect enterprise and personal sources: Microsoft 365, Google Workspace, cloud storage, databases, meeting recordings, Notion, code repositories and on-premise file servers through indexer agents.

  • Microsoft 365
  • Google
  • Databases
  • On-prem agents
Capabilities

Everything in the platform

7 modules, built from scratch for our partner and run in production by our team.

01

Integrations

Connect enterprise and personal sources: Microsoft 365, Google Workspace, cloud storage, databases, meeting recordings, Notion, code repositories and on-premise file servers through indexer agents.

  • Microsoft 365
  • Google
  • Databases
  • On-prem agents
  • Connect at enterprise level for the whole organisation, or individually for each user
  • Microsoft5
    • Outlook
    • OneDrive
    • SharePoint
    • Teams
    • Azure Blob Storage
  • Google3
    • Google Drive
    • Gmail
    • Google Cloud Storage
  • AWS S3
  • File indexer agents3
    • Windows (on-prem)
    • Linux (on-prem)
    • macOS (on-prem)
  • Zoom
  • Databases5
    • MaxDB
    • PostgreSQL
    • Microsoft SQL Server
    • MySQL
    • Neo4j
  • Notion
  • Code repository upload
02

Ingestion pipeline

A fast pipeline that handles documents, email, images, audio, video, archives, code and structured data. It splits large items into usable chunks, prepares analytical data for no-code analytics, removes duplicates and keeps per-user access intact.

  • Custom OCR
  • Speech to text
  • De-duplication
  • Handles documents, email, images, audio, video, archives, code and structured data
  • Splits large data entities into smaller, usable chunks
  • Prepares analytical data for no-code, real-time analytics
  • De-duplicates identical data entities
  • Maps users to data entities so access stays individual
  • Custom OCR1
    • Scanned PDFs and images
  • Custom speech to text1
    • Audio and video
  • Real-time ingestion overviews
03

AI-governed enrichment

Every item is classified against your own ontology or one the AI infers, then summarised, scored for sensitivity and business criticality, and tagged with usable metadata.

  • Classification
  • Sensitivity
  • Criticality
  • Works with an explicit customer ontology and an implicit, AI-inferred ontology
  • Classification and sub-classification
  • Summaries of each data entity
  • Sensitivity analysis
  • Metadata extraction
  • Business criticality analysis
04

Sensitivity write-back

A rule engine writes the sensitivity label of each governed item back to its original source, with rules you control, such as only ever upgrading a label.

  • Rule engine
  • Source labels
  • Custom rules
  • Rule-based engine that writes sensitivity back to the original source
  • Editable write-back rules, for example upgrade labels only and never downgrade
05

Search, RAG and chat

Find any file across every source in seconds, ground AI answers in your own data (retrieval-augmented generation, or RAG) with an enterprise vector index, and chat with documents or run live analytics on structured data.

  • Enterprise RAG
  • Advanced search
  • Chat analytics
  • Enterprise vectorised retrieval-augmented generation (RAG)
  • Fast advanced file search for teams and individuals
  • Chat with AI using your data2
    • Chat with unstructured data entities
    • Real-time chat-based analytics on structured data
06

AI-governed retention

The AI finds explicit and implicit retention details, such as what triggers expiry and when, and deletes expired data at the source once a person approves.

  • Retention metadata
  • Human approvals
  • Overviews
  • Extracts explicit and implicit retention metadata, such as expiry triggers and dates
  • Deletes original data from connected sources after human approval
  • Real-time retention overviews
07

Human oversight and alerting

People stay in control. Classification overrides, label changes, write-back runs and deletions wait for approval with the AI reasoning attached, and proactive alerts flag what needs attention.

  • Human in the loop
  • Approvals
  • Proactive alerts
  • Human in the loop at each step4
    • Classification and ontology overrides
    • Sensitivity label changes
    • Write-back runs
    • Deletion at the source
  • Proactive alerting, for example sensitive files in open shares, failed ingestion or retention due
Connects to

Sources and feeds

Microsoft

  • Outlook
  • OneDrive
  • SharePoint
  • Teams
  • Azure Blob

Google

  • Drive
  • Gmail
  • Cloud Storage

Cloud and apps

  • AWS S3
  • Zoom
  • Notion
  • Code repositories

Databases

  • MaxDB
  • PostgreSQL
  • SQL Server
  • MySQL
  • Neo4j

On-premise agents

  • Windows
  • Linux
  • macOS
Delivery and operations

How we built and run it

  • Runs in the cloud, on premise or as a hybrid, with indexer agents inside the customer network.
  • Data stays in its sources and chosen region. The platform stores only the index and metadata it creates.
  • Search and chat answers respect each person's existing access, and every approval and deletion is logged.
  • Self-hosted models handle content that is too sensitive to leave the environment.
  • Built from scratch by SparkAi, which still runs releases, monitoring and new features.